About Helicone
Overview
Helicone is an AI gateway and LLM observability platform that helps teams route, debug, and analyze their AI applications. It sits between your application and LLM providers like OpenAI, Anthropic, and Azure, giving you visibility into every request.
The fastest-growing AI companies use Helicone to monitor performance, manage costs, debug issues, and control how their apps interact with language models. The platform combines an API gateway with observability tooling, including caching, rate limits, automatic fallbacks, and a query language for analyzing request data.
Key Benefits
- Integrated with 8+ LLM providers including OpenAI, Anthropic, Azure, LiteLLM, Anyscale, Together AI, OpenRouter, and more.
- Tracks and visualizes requests, sessions, users, and custom properties across all LLM calls.
- Reduces latency by caching responses — saved 386 hours for one customer by using cached responses.
- Detects critical bugs automatically, reducing agent runtime by 30% in one documented case.
- Offers flexible pricing with a free Hobby tier (10,000 requests/month) and usage-based plans that scale with your team.
- Open-source with a single-line integration to get started quickly.
How It Works
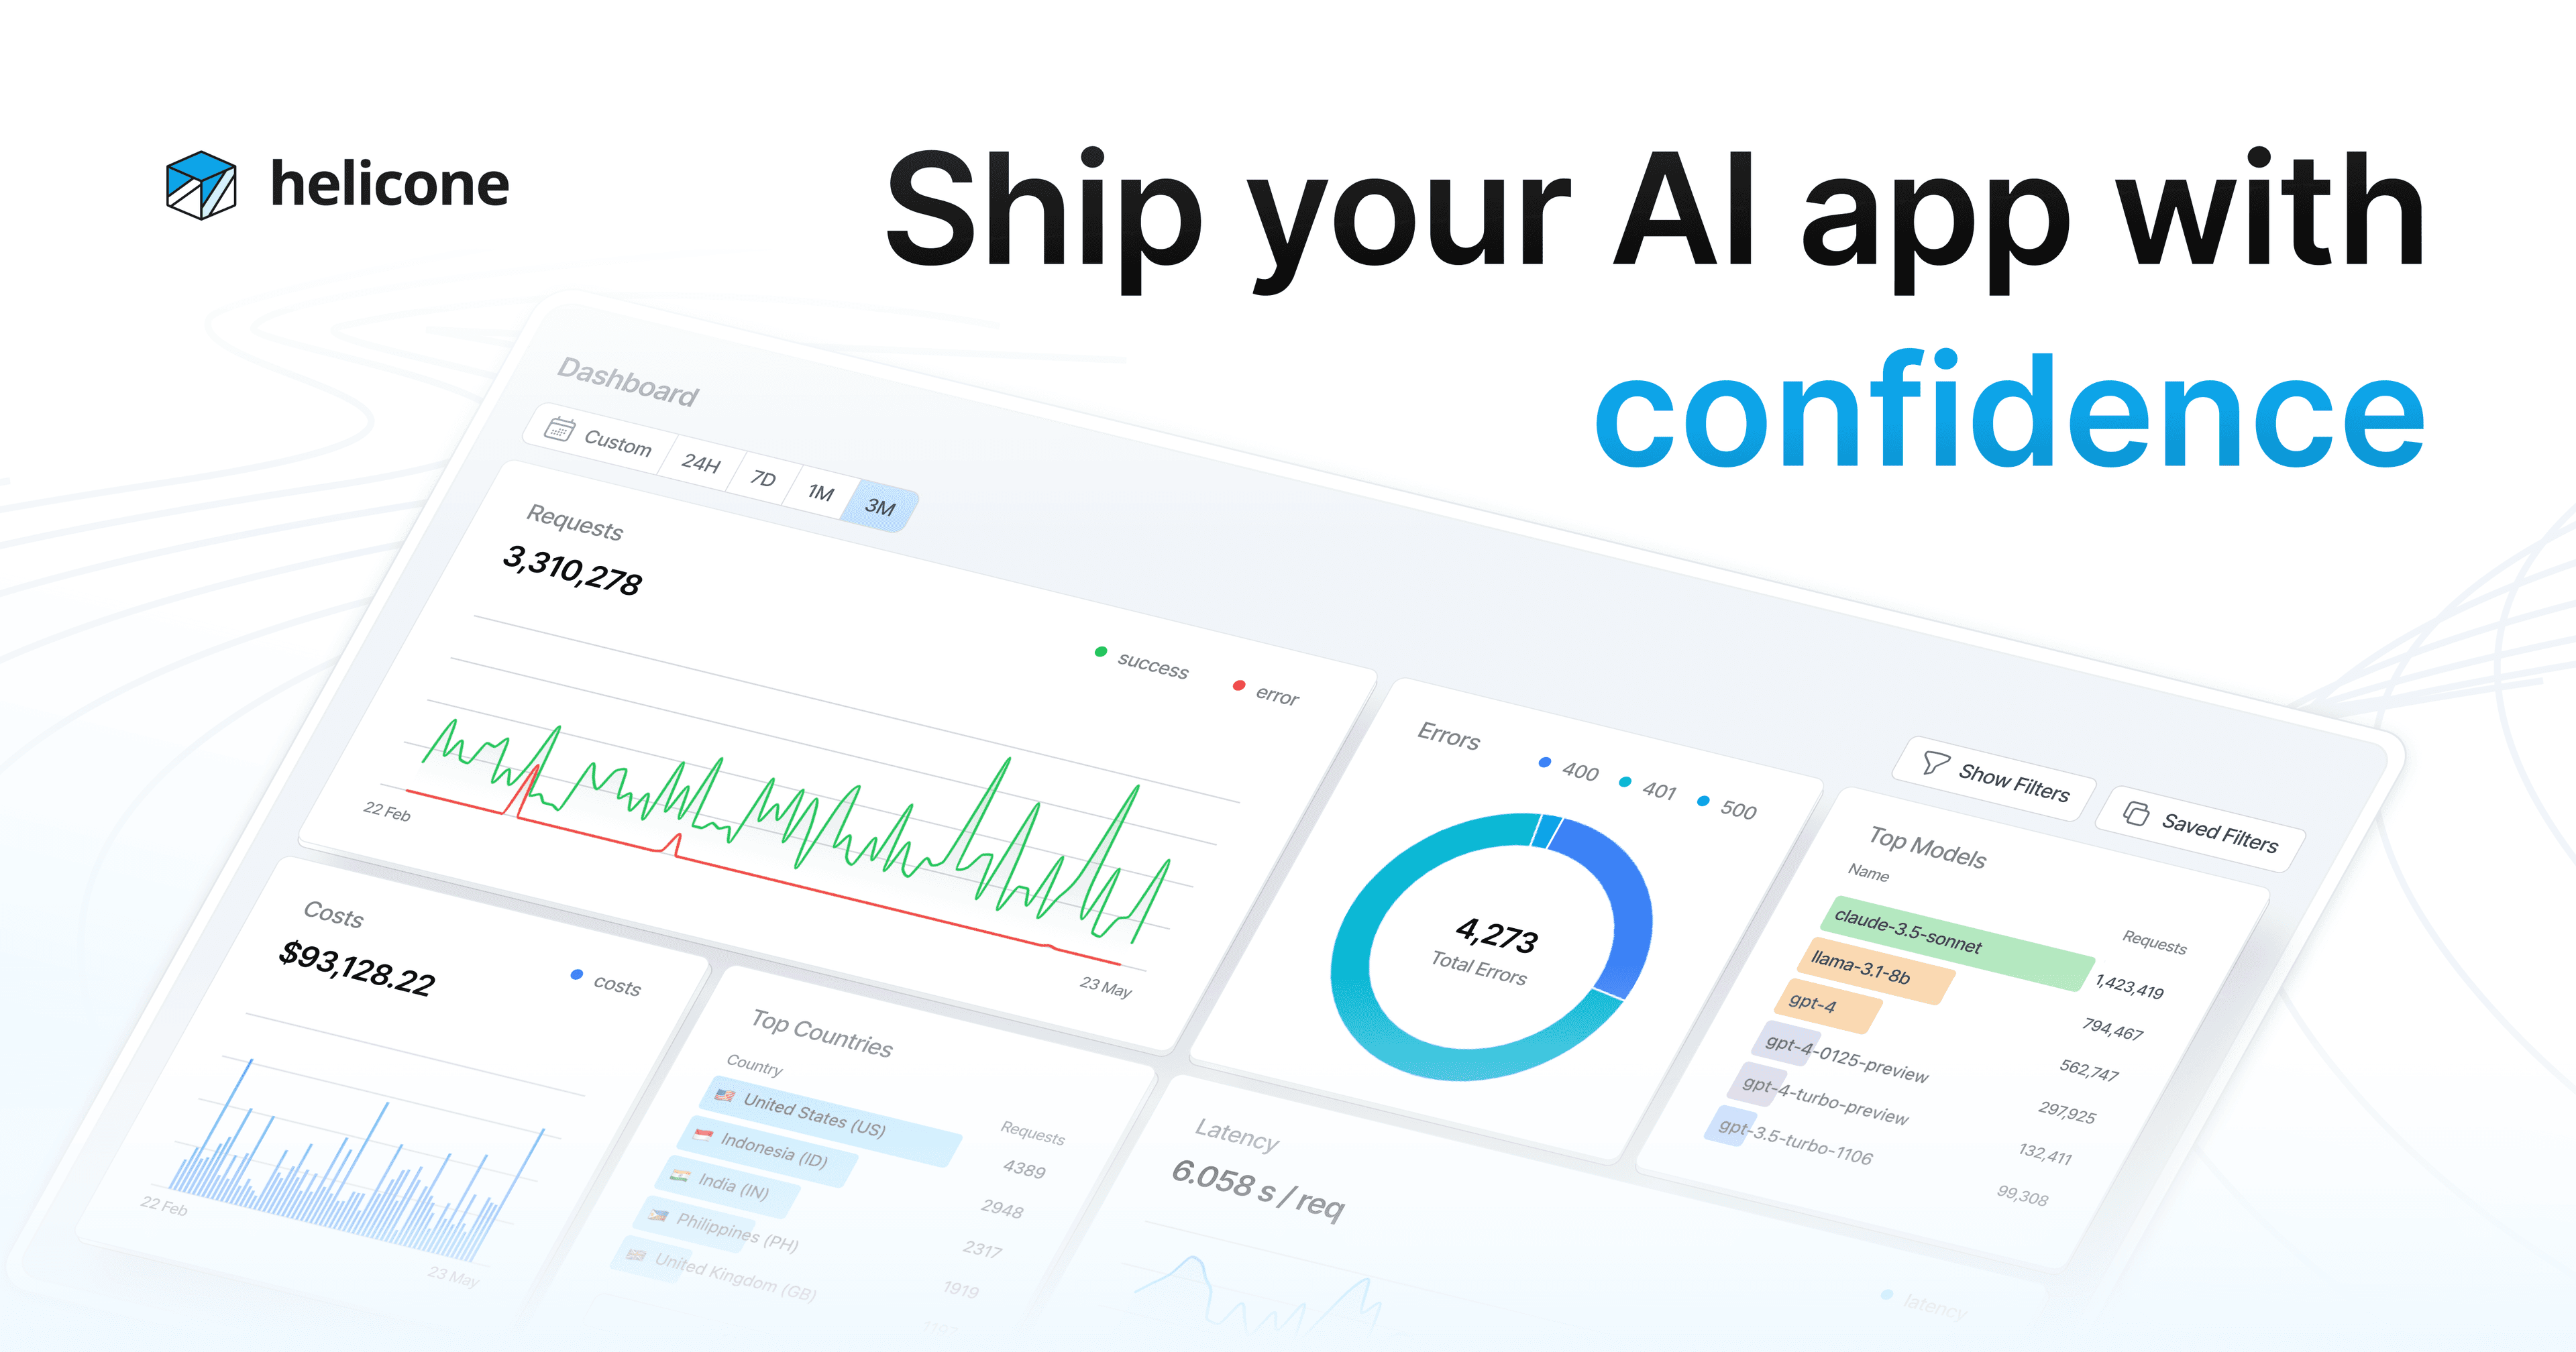
You add Helicone as a proxy between your application code and your LLM provider with a single-line integration. Every request and response is logged automatically, and you view them in the Helicone dashboard where you filter by sessions, users, custom properties, or write queries using HQL (Helicone Query Language).
You set up rate limits, automatic fallback to alternative providers, and caching rules through the dashboard or API. Alerts and reports notify your team when usage spikes or errors occur.
Use Cases
- AI engineering teams — monitor every LLM call in production to debug failures and track latency across providers.
- Startups building AI-powered products — manage costs with usage-based pricing and caching while scaling from prototype to production.
- Compliance and security officers — enforce HIPAA and SOC-2 compliance through dedicated plans with SAML SSO and on-prem deployment.
- Platform teams at growing companies — route traffic across multiple LLM providers with automatic fallbacks and rate limits for reliability.
- Open-source project maintainers — integrate a free observability layer into their AI applications with the community edition.
Why Choose This Product
Helicone is best suited for teams that need provider flexibility, cost control, and deep observability across their AI stack. It competes with LangSmith by offering broader provider support and open-source availability. Usage-based pricing at scale means costs grow predictably with request volume.
Helicone Pros & Cons
- Integrates with 8+ major LLM providers
- Open-source with single-line integration
- Free Hobby tier with 10,000 requests/month
- Usage-based pricing scales with volume
- SOC-2, HIPAA, and SAML SSO available on Team plan
Key Features
AI Gateway Routing
Routes LLM requests across multiple providers with automatic fallbacks and caching to improve reliability and reduce latency.
Request Dashboard
Visualizes every LLM request and response with filtering by sessions, users, custom properties, and HQL queries.
Response Caching
Caches LLM responses to reduce latency and costs, saving one customer 386 hours of processing time.
Rate Limiting
Sets rate limits on API requests to control usage and prevent cost overruns across your organization.
Automatic Fallbacks
Falls back to alternative LLM providers automatically when the primary provider fails or returns errors.
Alerts & Reports
Sends alerts and generates reports when usage spikes, errors occur, or other configured thresholds are breached.
Playground & Prompts
Provides a playground for testing prompts and managing prompt templates with versioning and datasets.
HQL Query Language
Lets users write custom queries against LLM request data using Helicone Query Language for deep analysis.
Session & User Tracking
Tracks individual user sessions across multiple requests to understand end-to-end AI application behavior.
Helicone Pricing
View full pricing →- 10,000 free requests per month
- 1 GB storage
- 1 seat, 1 organization
- 7-day data retention
- Community support on GitHub and Discord
- Everything in Hobby
- Unlimited seats
- Alerts & reports
- HQL (Query Language)
- 1-month data retention
- Chat & email support
- Everything in Pro
- 5 organizations
- SOC-2 & HIPAA compliance
- Dedicated Slack channel
- 3-month data retention
- Configurable retention
- Everything in Team
- Custom MSA
- SAML SSO
- On-prem deployment
- Bulk cloud discounts
- Forever data retention
| Feature | Hobby Free/mo | Pro $79/mo | Team $799/mo | Enterprise Custom |
|---|---|---|---|---|
| 10,000 free requests per month | ||||
| 1 GB storage | ||||
| 1 seat, 1 organization | ||||
| 7-day data retention | ||||
| Community support on GitHub and Discord | ||||
| Everything in Hobby | ||||
| Unlimited seats | ||||
| Alerts & reports | ||||
| HQL (Query Language) | ||||
| 1-month data retention | ||||
| Chat & email support | ||||
| Everything in Pro | ||||
| 5 organizations | ||||
| SOC-2 & HIPAA compliance | ||||
| Dedicated Slack channel | ||||
| 3-month data retention | ||||
| Configurable retention | ||||
| Everything in Team | ||||
| Custom MSA | ||||
| SAML SSO | ||||
| On-prem deployment | ||||
| Bulk cloud discounts | ||||
| Forever data retention |
Pricing extracted from the product website and may change. Check the source for current details.
Frequently asked questions about Helicone
What do I get with the free plan?
The Hobby plan gives you 10,000 free requests per month, 1 GB storage, 1 seat with 1 organization, 7-day data retention, and community support on GitHub and Discord.
How is Helicone's usage-based pricing calculated?
Usage-based pricing applies on Pro and Team plans beyond the included 10,000 free requests and 1 GB storage. You can estimate monthly costs using the pricing calculator on the pricing page.
Can I switch plans or cancel anytime?
Yes, you can switch plans or cancel anytime. Pro and Team plans include a 7-day free trial to test the features before committing.
Do you offer discounts for startups, students, or open source projects?
Yes. Startups under 2 years old and with under $5M in funding get 50% off the first year. Non-profits get discounts based on org size. Open-source companies get a $100 credit for the first year. Students get free access.
Is Helicone free?
Helicone offers a free plan with optional paid upgrades. See the pricing section for what's included in each tier.
How much does Helicone cost?
Helicone offers the following plans: Hobby, Pro, Team, Enterprise. See the pricing section for what's included in each tier and any per-seat or usage-based costs.
How Helicone compares
HeliconeThis | ||
|---|---|---|
| Starting price | Free | Free |
| Pricing model | Freemium | Freemium |
| Platforms | — | Web |
| Top features |
|
|
| Rating | — | — |